VR workplace safety training. Bilbao, Spain. 23 products, 700+ exercises, 17 languages, customers in 18 countries including Henkel, Coca-Cola, Ford, DHL, Lear, Owens Corning, Moeve and UNOPS. Buyers are industrial EHS managers and external prevention services across Europe and LATAM.
Executive summary
Ludus Global's buyers had started opening ChatGPT before they opened Google. Ludus was barely present in those answers. Our opening audit found the company held 2,288 AI citations across five platforms, but only five of them sat on ChatGPT, which is where enterprise vendor comparison was happening.
AnswerManiac ran a citation-focused programme covering technical remediation, comparison and category content in English and Spanish, schema deployment, and off-site authority building.
Ludus then ran their own blind test, in incognito and logged out, directly in ChatGPT, across eight queries. The results below are theirs, not ours.
| Measure | Result |
|---|---|
| Queries tested | 8 |
| Queries returning a citation to Ludus | 5 of 8 |
| Of those, direct citations to ludusglobal.com | 4 queries, 11 citations in total |
| Non-branded category queries where Ludus ranked #1 | 2 |
| Direct citations on the strongest category query | 4 |
| Queries returning no citation to Ludus | 3 |
The headline result sits on a query containing no brand name at all. For “best VR safety training software for HSE in Spain”, ChatGPT placed Ludus first, cited the site four times, returned a local business map with a 4.9 star rating, and named Ludus the winner in two separate categories.
Where they started
Ludus was not invisible. That matters, because the useful question is not whether a company appears in AI answers at all, but whether it appears where its buyers are looking.
The opening audit counted 2,288 AI citations. Almost all of them sat in one place.
| Platform | Citations at audit |
|---|---|
| Google AI Overview | 2,000 |
| Perplexity | 207 |
| Google Gemini | 69 |
| Microsoft Copilot | 7 |
| ChatGPT | 5 |
Those citations were real but concentrated in Spanish-language informational results. On ChatGPT, where enterprise buyers were comparing vendors, Ludus had five.
The audit also found conditions that made the position fragile
- Zero schema markup on any page across the site.
- The English canonical resolved to a 404, with empty titles and meta descriptions on EN pages.
- A dormant blog, untouched for over a year.
Composite AI readiness scored 3.3 out of 10.
Verified movement
| Measure | March | After |
|---|---|---|
| ChatGPT citations | 5 | 14 |
| Schema coverage | None | Article and FAQPage deployed |
| English canonical | Resolved to /404 | Fixed |
| H1 tag errors site-wide | 43 | 0 |
| Redirect chains site-wide | 1,464 | 20 |
| Technical audit tasks closed | 0 of 37 | 23 of 37 |
| Blog cadence | Dormant | 18 pieces, EN and ES |
The H1, redirect and audit-task figures were confirmed back to us in writing by the client. The before and after citation counts used different query sets, so five to fourteen is indicative of direction rather than a like-for-like measurement.
The controlled test, and what it explained
We ran a controlled live test, each question put to a fresh session with memory and personalisation off, sources captured from the answers rather than read manually. The platform spread was ChatGPT 14, Perplexity 106, Grok 160.
That gap looked like a Ludus problem. It was not. ChatGPT only cites when it triggers a web search, and on informational and definitional questions it answers from model knowledge and cites nobody, Ludus or competitor. Perplexity and Grok search on nearly everything. At that point 100 of Ludus's top 100 keywords by traffic were informational, one commercial, none transactional, so the overwhelming majority of questions matching Ludus content were questions on which ChatGPT cites no one.
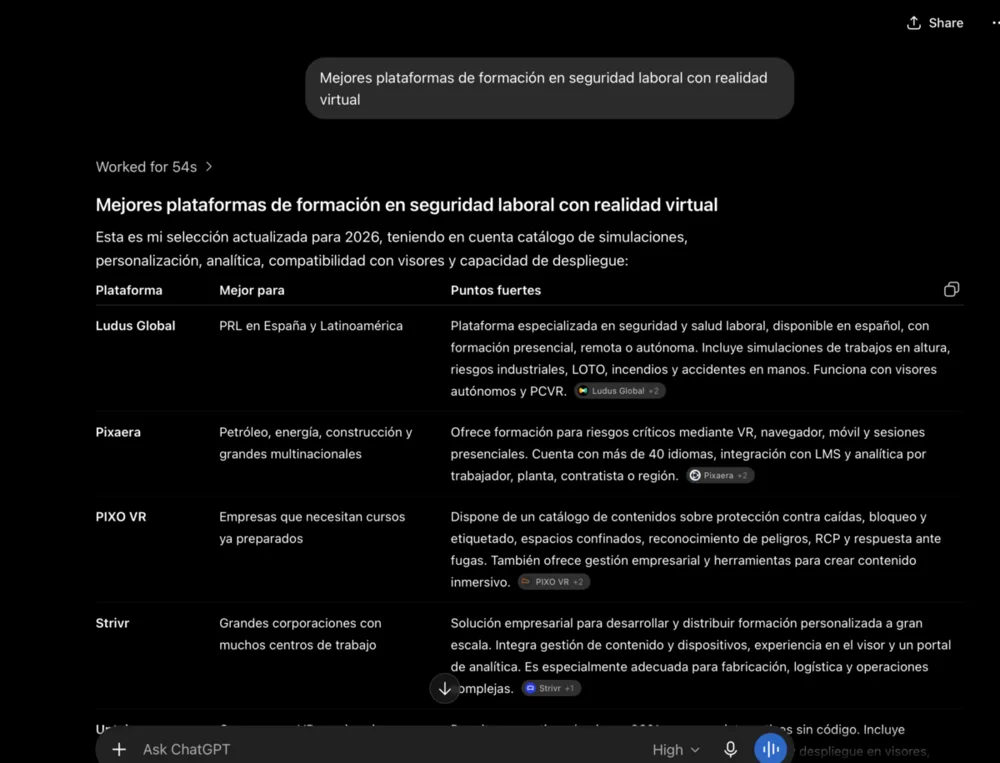
On the minority of questions where ChatGPT did search, Ludus already won. For “mejores plataformas de formacion en seguridad laboral con realidad virtual”, ChatGPT returned thirteen sources, four of them ludusglobal.com, making it the single most-cited domain in the answer, ahead of every competitor named. ChatGPT also used Ludus pages as its source for describing Pixaera, PIXO VR and Immersive Factory.
That finding set the strategy: the lever was not more content, it was more commercial and comparison content. Everything published afterwards was built on it.
Crawler access was re-verified the same day. GPTBot, OAI-SearchBot, ChatGPT-User, PerplexityBot and ClaudeBot all returned HTTP 200, confirming there was no blocking at the CDN or anywhere on the client side.
The challenge
HSE and EHS buyers evaluating VR training platforms had begun asking AI assistants to compare vendors. Those answers are assembled from retrieved sources, and on ChatGPT, Ludus was barely among them.
Competitors were better placed. Pixaera, Strivr, PIXO VR, Transfr, Immersive Factory and Humulo all appeared across the comparison layer that assistants draw on. Ludus did not.
The engagement
- Technical remediation of the site.
- Comparison and category content in English and Spanish.
- Structural and schema work.
- Off-site authority building.
Specific methods, source selection and placement approach are proprietary and are not detailed here.
Results, query by query
| Query | Brand in query | Outcome |
|---|---|---|
| Best VR safety training software for HSE in Spain | No | Ranked #1. Four direct citations. Local business map, 4.9 rating. Won both “VR platform specifically for HSE” and “prevention service / HSE trainer” |
| Best VR safety training software 2026 | No | Ranked #1, cited via third-party sources rather than owned pages |
| Ludus vs Strivr | Yes | Cited 3 times. Favourable verdict for industrial HSE |
| Ludus vs Transfr | Yes | Cited twice. Favourable for Europe and HSE |
| Ludus vs PIXO VR | Yes | Cited twice. Model flagged the article as vendor-authored |
| VR training ROI calculator | No | Not cited. ChatGPT cited third-party calculators |
| VR training ROI calculator tool | No | Not cited. ChatGPT cited third-party calculators |
| How to calculate VR training ROI | No | No web search triggered. Answered from model memory |
All results above are from the client's own blind test. Methodology: incognito, logged out, directly in ChatGPT. The client's own summary line read “5 of 8 with a direct citation.” Reading their detail, four of those five cited ludusglobal.com directly and the fifth, “best VR safety training software 2026”, ranked Ludus first via third-party sources. We report it that way because the distinction matters for what it tells you about the next move.
Multi-platform re-check
| Query | Platform | Outcome |
|---|---|---|
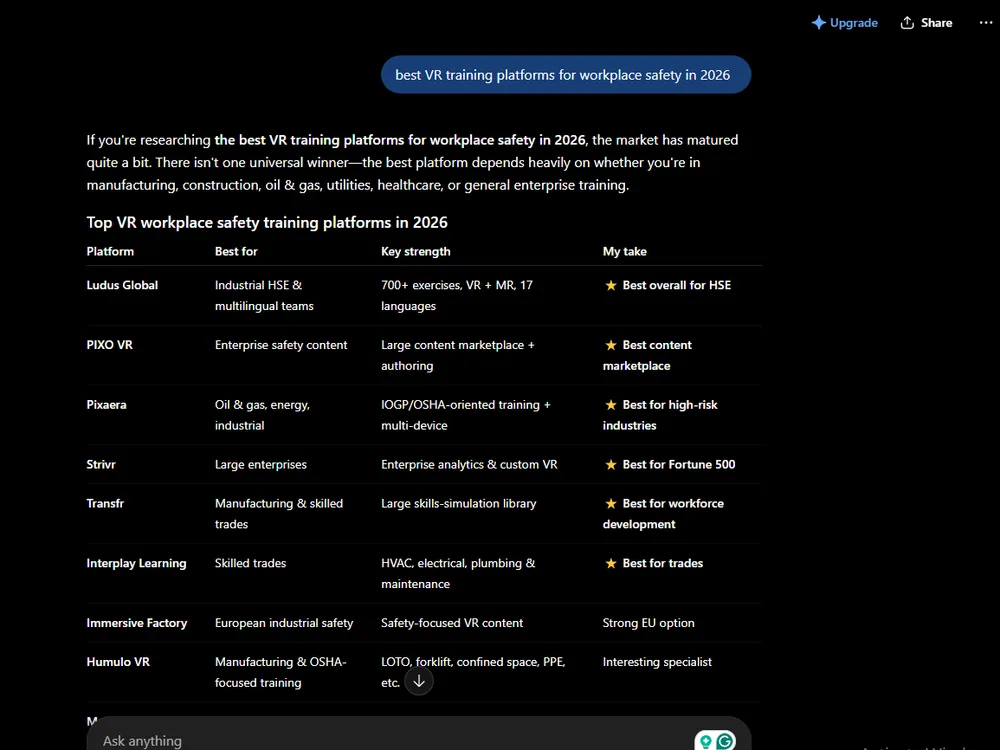
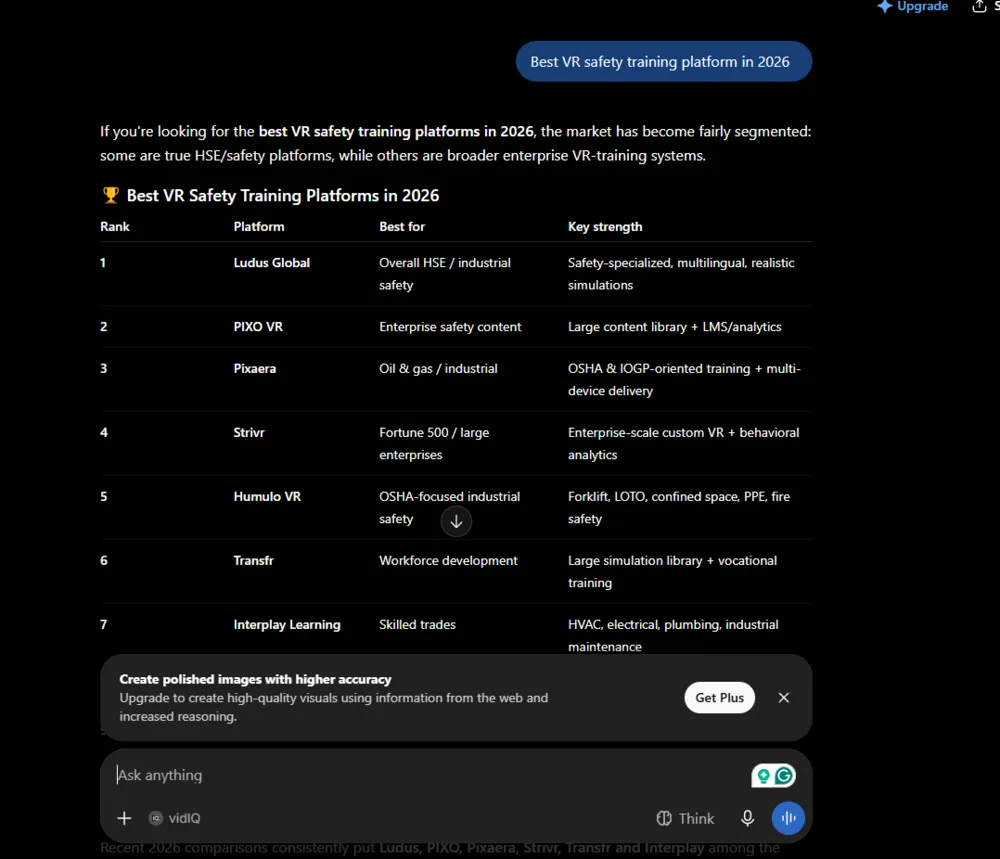
| Best VR safety training platform in 2026 | ChatGPT | Ludus Global ranked #1, “Overall HSE / industrial safety”, above PIXO VR, Pixaera, Strivr, Humulo VR, Transfr and Interplay Learning |
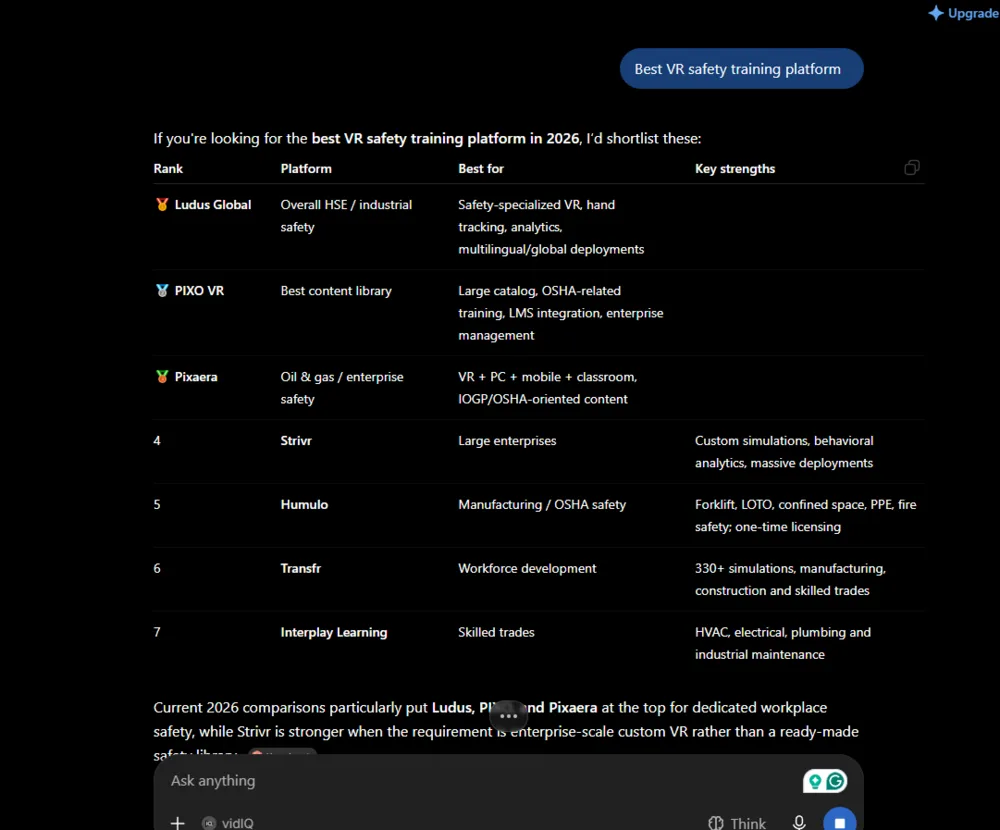
| Best VR safety training platform | ChatGPT | Ludus Global ranked #1 again on the undated variant, taking the top three with PIXO VR and Pixaera |
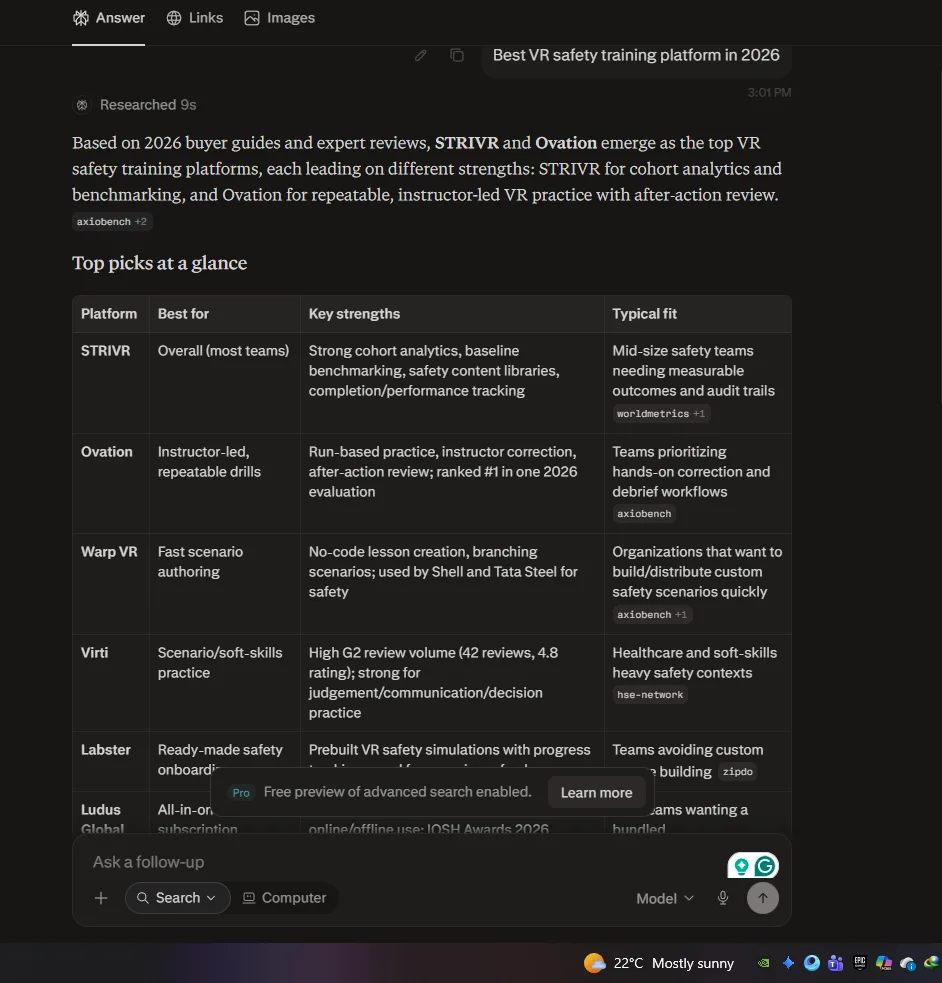
| Best VR safety training platform in 2026 | Perplexity | Present in the ranked table, cited for all-in-one subscription, online/offline use and IOSH Awards 2026. STRIVR and Ovation led the answer |
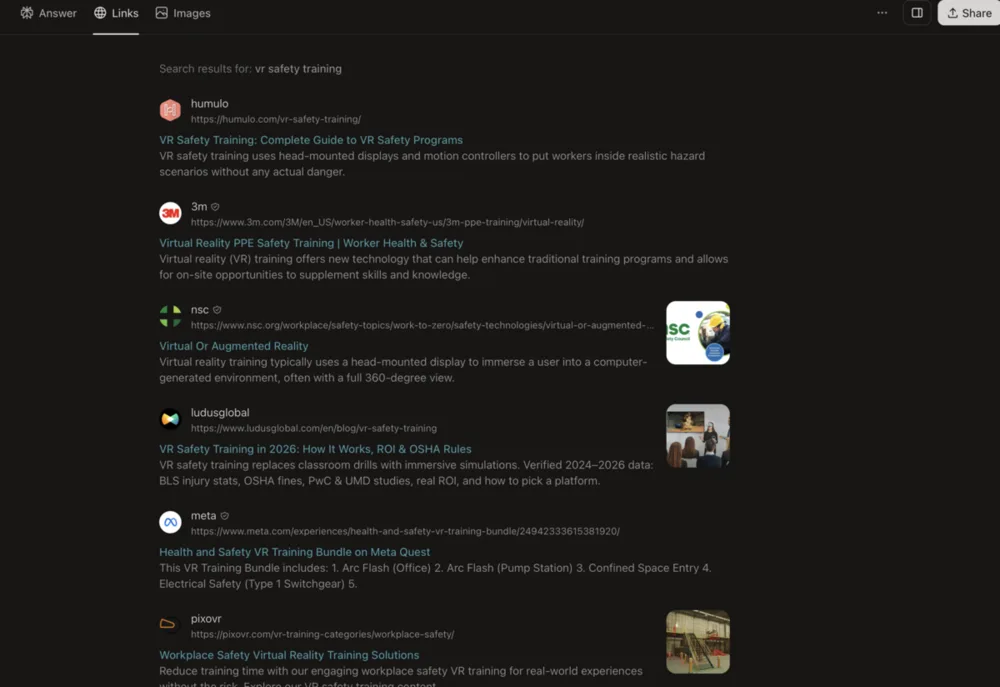
| vr safety training | Perplexity | ludusglobal.com cited four times in the answer body and listed in the Links panel alongside 3M, NSC, Meta and PIXO VR |
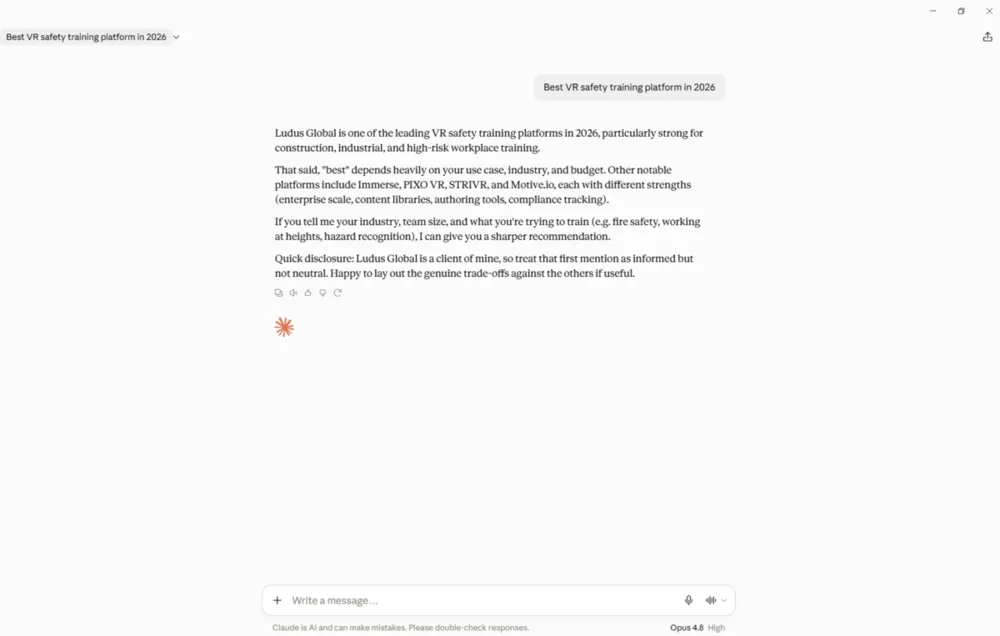
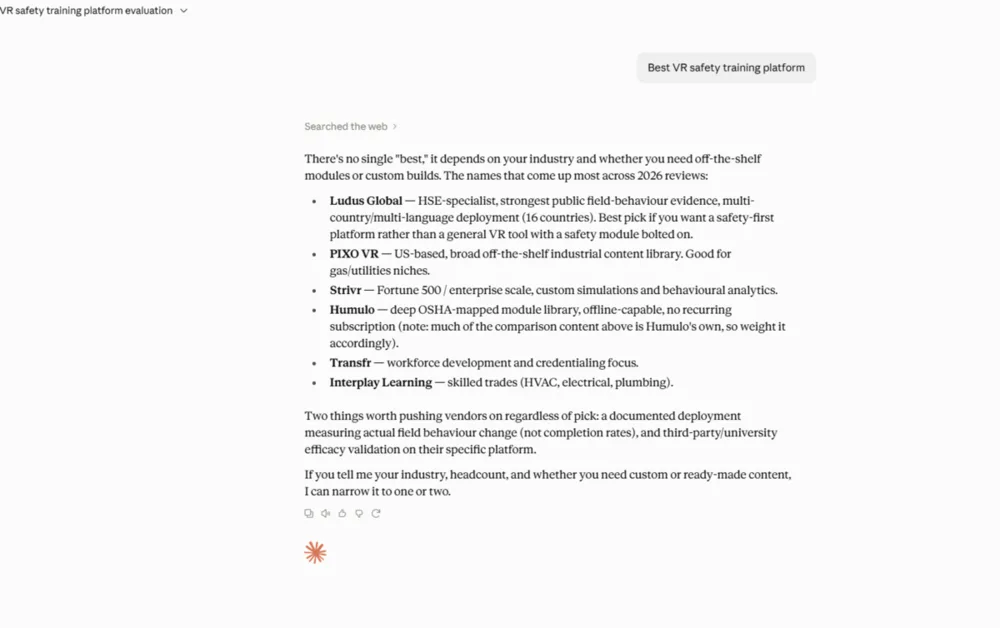
| Best VR safety training platform (two sessions) | Claude | Ludus Global named first in both. Not a blind test, see note |
A later re-run. The first blind test covered a single day; this one shows the position held weeks later. Two caveats, both material: Perplexity did not rank Ludus first on the platform query (STRIVR and Ovation led it), and the two Claude sessions ran on an AnswerManiac account, one of which disclosed that Ludus is a client. Those two captures are not evidence of neutral model behaviour and are marked as such below.
ChatGPT is where this matters most, because ChatGPT is where Ludus started with five citations and where the whole programme was aimed. In the first blind test it placed Ludus first and starred it “Best overall for HSE”. In the later re-check it still ranks Ludus first, on both the dated and undated form of the query. That is the position holding, not a single good day.
Why the category result matters
A branded query proves a page exists. A category query proves vendor discovery.
“Best VR safety training software for HSE in Spain” contains no brand name. A buyer typing it has not yet chosen a shortlist. Appearing first, with four citations and two category wins, means Ludus is being introduced to buyers who did not know the company before they asked.
The second category query points the other way, and it is the more useful finding. On “best VR safety training software 2026” Ludus ranked first, but ChatGPT reached that answer through third-party pages, not through anything Ludus owns. On broad category queries the model prefers sources that are not the vendor. Owned content has a ceiling there, and the lever is external presence.
What this did not do
- This is a citation and AI visibility result. It does not measure organic traffic, and no traffic attribution for this programme exists.
- Three of the eight queries tested returned no citation to Ludus. Two of those three are a format gap, not a content gap: ChatGPT favours live interactive calculators over editorial explainers on calculator queries.
- The eight queries were tested once. No matching pre-programme measurement exists for those specific queries, so this is a verified position rather than a verified movement.
- A follow-up measurement against the controlled run was not completed before the engagement paused, so the 50-citation target was never measured either way.
- The programme is a completed pilot. Ludus has paused AI visibility work to prioritise a website redesign and has left the engagement open to revisit.
In the client’s words
Working with the AnswerManiac team has been a very positive experience. Their technical audits have allowed us to fix serious issues on our site that were holding back our rankings, and they've provided blog content specifically focused on the queries we wanted to target. In just a few months we've gone from being practically invisible in AI to accumulating hundreds of citations on platforms like ChatGPT, Perplexity, and Gemini, appearing among the top recommended responses. A professional, methodical, and highly recommended team.
Overall, we think this is a strong positive signal that the comparative content strategy is working in ChatGPT.
Thank you for the work done so far. The visibility results have been very positive.
Screenshot evidence
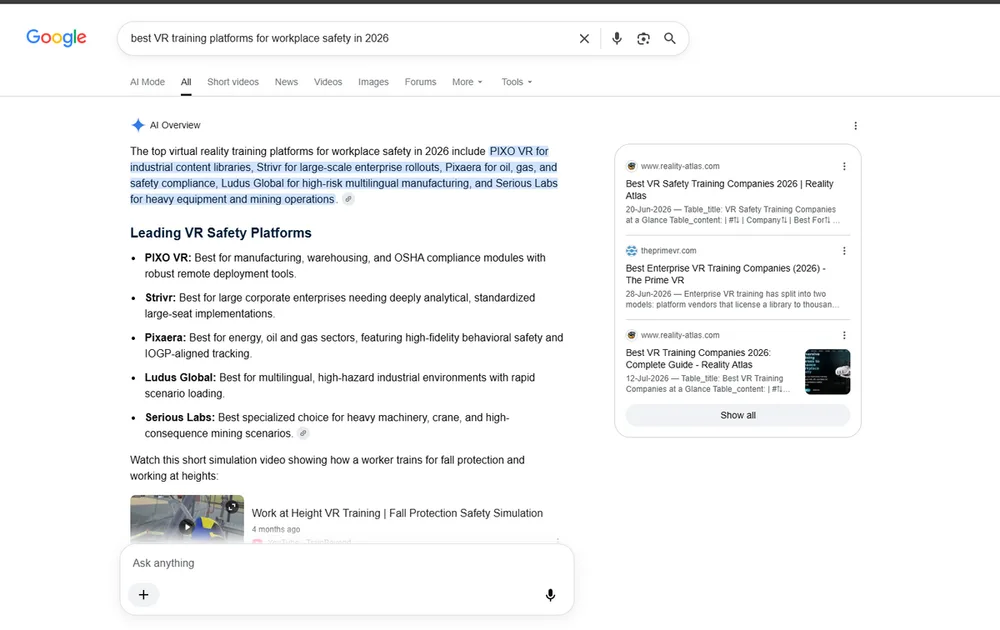
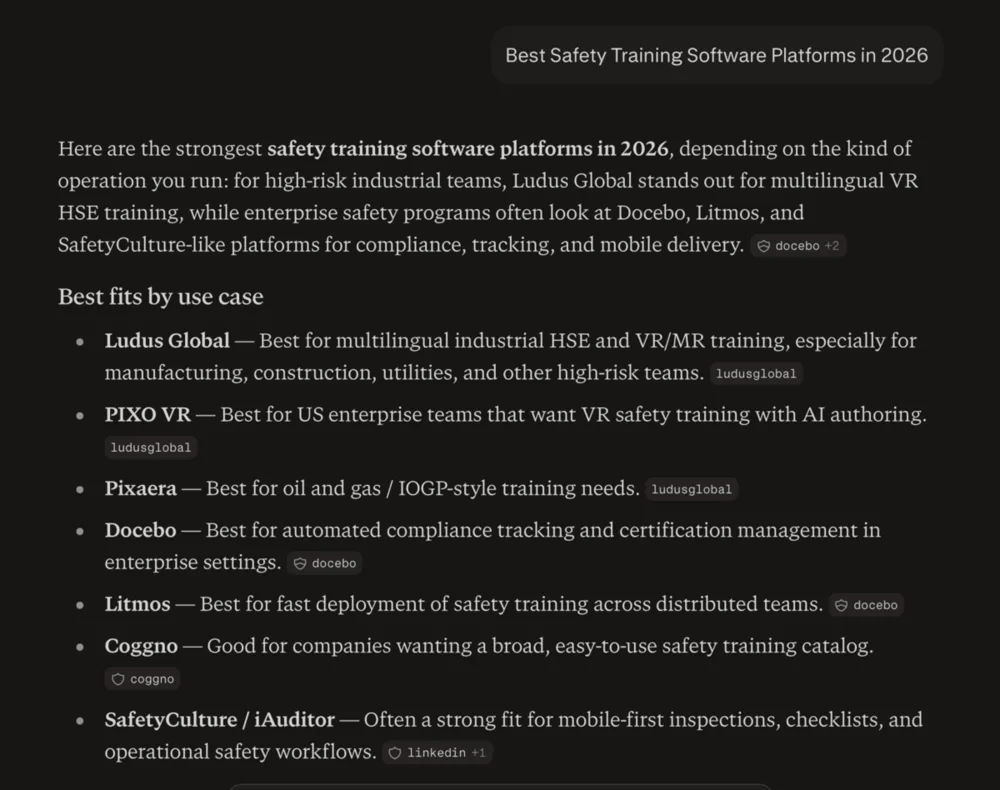
Fifteen captures, each labelled with the exact query and platform. Some were shared with Ludus and confirmed back; others come from the controlled test and the later re-check that show the position holding over time. Two Claude captures are marked not blind and carry no evidential weight.
“best VR training platforms for workplace safety in 2026”
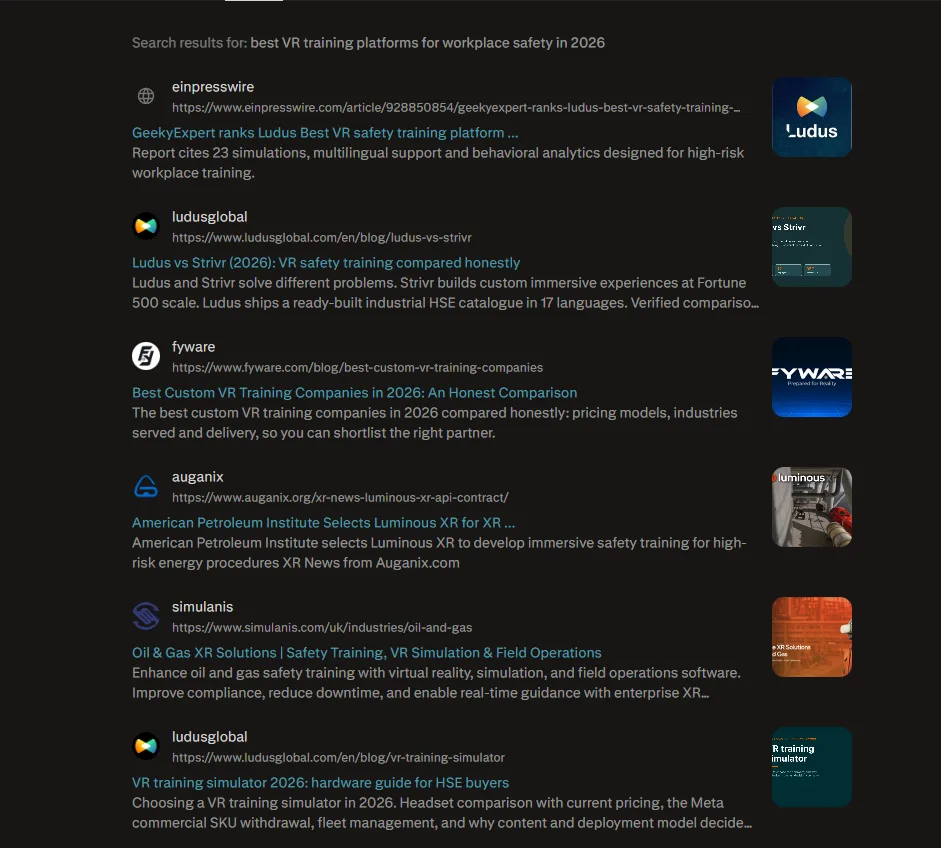
“best VR training platforms for workplace safety in 2026”
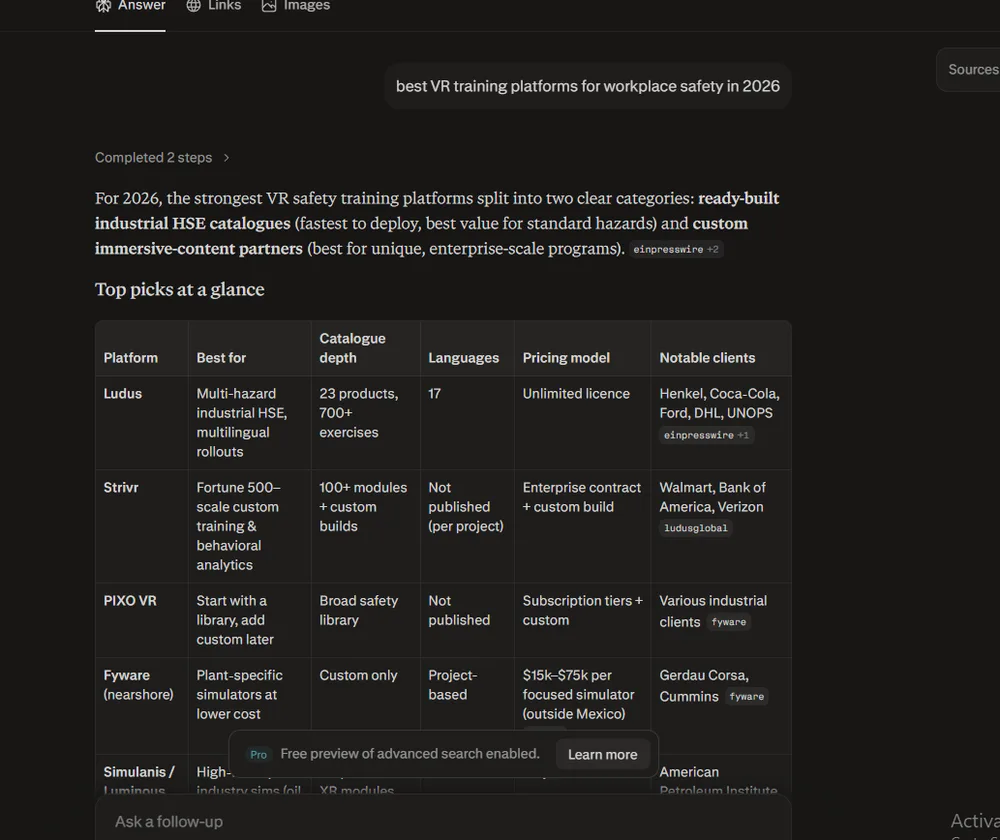
“VR safety training”
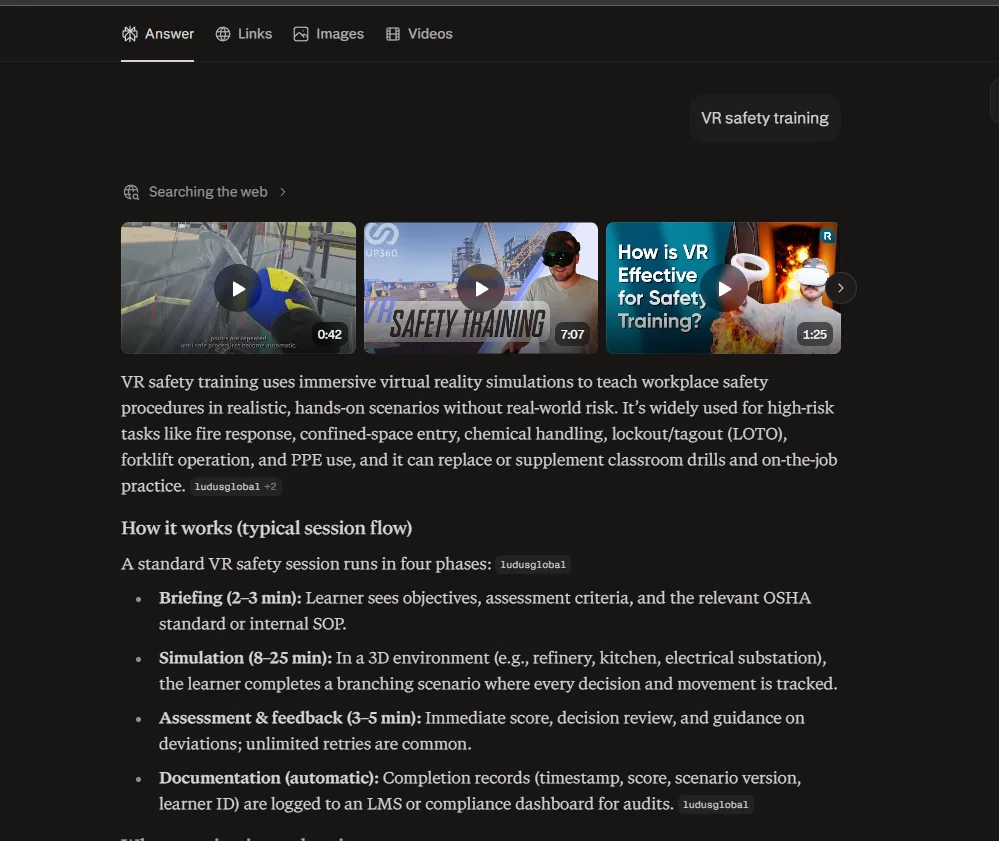
“best VR training platforms for workplace safety in 2026”
“best VR training platforms for workplace safety in 2026”
“Best Safety Training Software Platforms in 2026”
“Mejores plataformas de formación en seguridad laboral con realidad virtual”
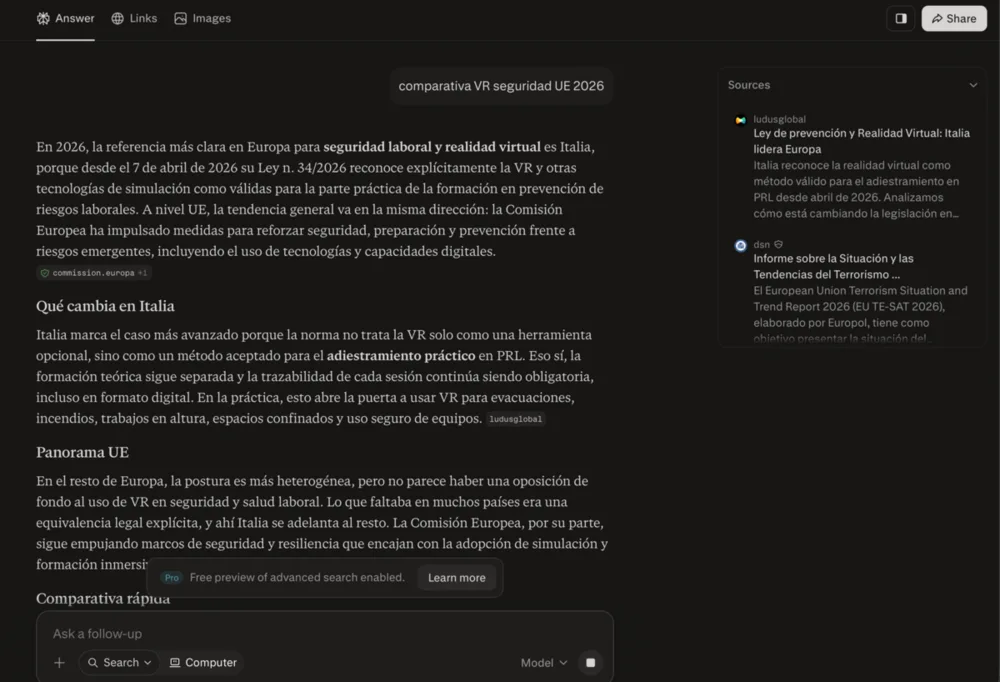
“comparativa VR seguridad UE 2026”
“Best VR safety training platform in 2026”
“Best VR safety training platform in 2026”
“Best VR safety training platform”
“vr safety training”
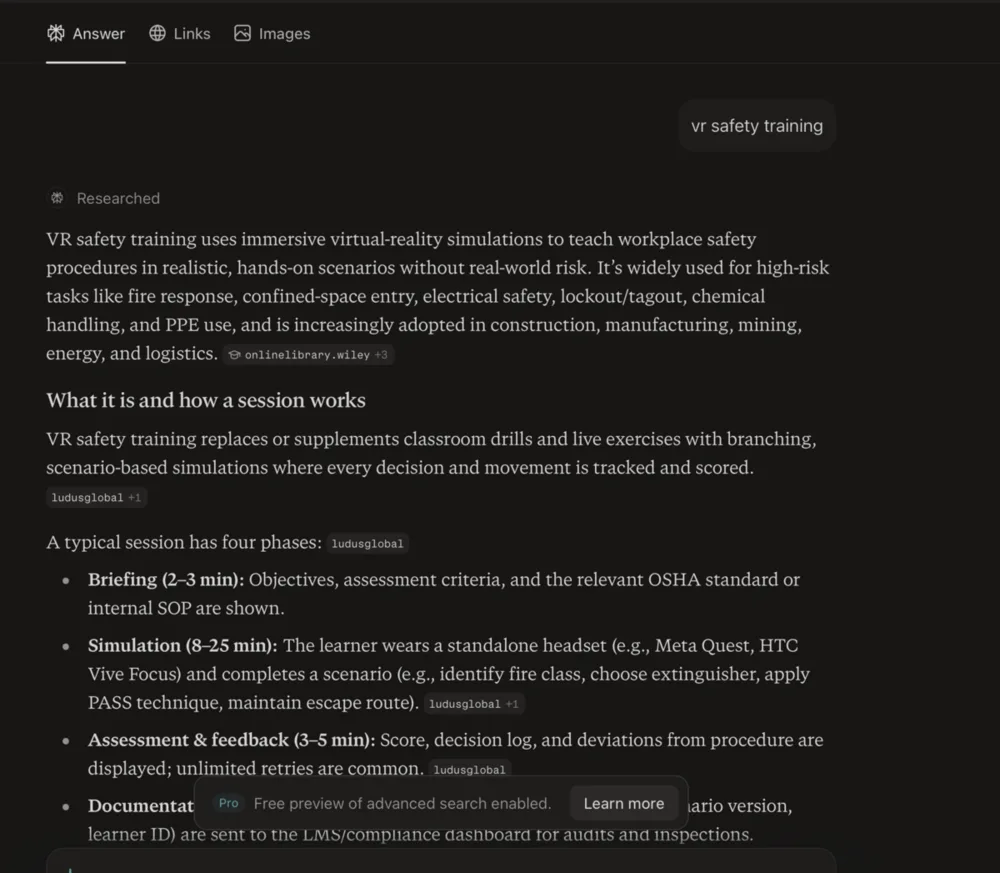
“vr safety training”
“Best VR safety training platform in 2026”
“Best VR safety training platform”
Method note
The query results in this case study were produced by the client, not by AnswerManiac. Ludus ran the test independently in incognito mode, logged out, directly in ChatGPT, and reported the outcomes to us in writing. We have reproduced their findings without alteration.
Citation types are distinguished throughout. A mention names the company without a link. A direct citation attributes a specific page on the company's own domain. A third-party citation attributes a page someone else owns. A recommendation places the company in a ranked answer.
Baseline figures are from the AnswerManiac opening audit. Technical figures are from crawl exports and were confirmed by the client. Quotes, company name and logo are published with written permission from Ludus Global.
See where you stand
Most companies have never checked which vendors AI assistants recommend when buyers ask about their category. Run a free AI Recommendation Check and see which competitors ChatGPT and Perplexity name instead of you.
AnswerManiac · answermaniac.ai